

Who Should Own The Knowledge That Underpins AI Technology?


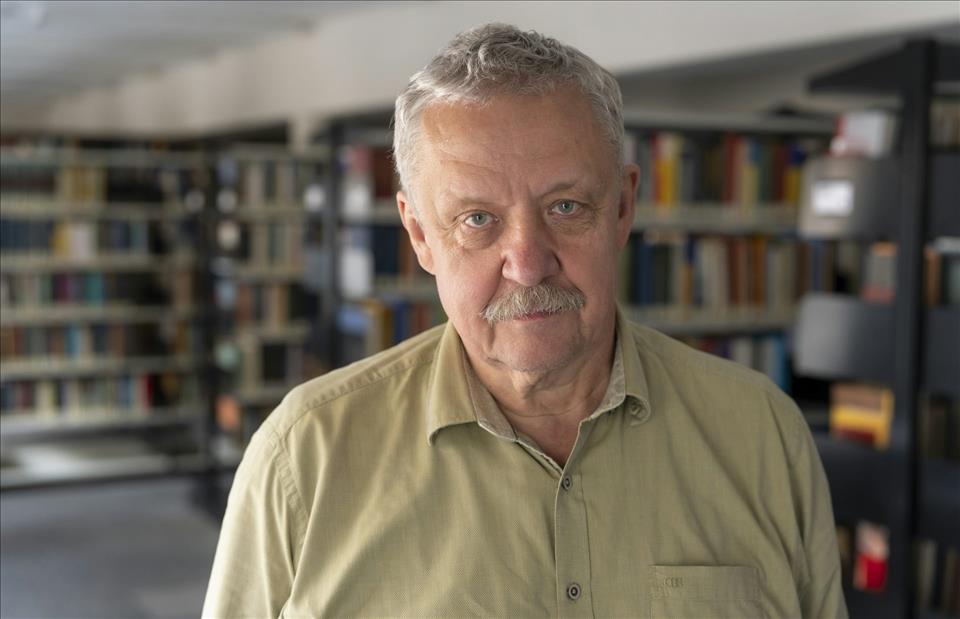
Everyone using large language model (LLM) chatbots such as ChatGPT, Claude and Gemini – for any purpose – depends on Nesterov's methods. They may speak like humans and be personified with names, but under the bonnet, LLMs are computer programs that work via optimisation of billions of parameters known as neural networks for their similarity to how brains function.
These pure mathematical systems are powered in part by gradient descent algorithms, or variants of them. Their development represents one of the biggest technological breakthroughs of the 21st century.
But where does the knowledge that underpins this technology come from – and who should be allowed to own it?
Why gradient descent is key to AI systemsIf you were standing in a mountain range and wanted to get to the bottom of a valley as fast as possible, you'd take steps downhill until you got there. Fundamentally, this is how gradient descent methods work.
For a given task with a set of parameters – such as how well an LLM can predict the next word in a sentence – the idea is that gradient descent provides a way to get to the best prediction, the point of minimum error, taking as few steps as possible. In our example, this point represents the most likely next word in the sentence.
Nesterov's contribution has been finding optimal ways to achieve this. One of his key insights is using momentum to help you get to the bottom of the valley faster – known as the Nesterov Accelerated Gradient method (here's a deeper explanation of the mathematics involved).
This work has made huge-scale optimisation feasible at workable speeds – thus underpinning the rapid development of LLMs, and AI systems more generally, over the last few years.
This technology is affecting more and more aspects of life. At home, AI agents are being touted as ways to manage busy households. In medicine, the first AI-assisted brain surgery was recently performed in a London hospital. In mathematics, AI-generated proofs claim to have solved a number of longstanding problems, with some referring to the AI agents as “collaborators” in this work.
All of this leads to big business. The race for AI dominance is built on massive capital and research and development expenditure, to develop the technology and supporting infrastructure required to support this global industrial revolution.
While in the west, private AI companies are bearing a sizeable part of this burden (without, in most cases, seeing any profits ), the role of publicly funded research is and will remain critical to their business models.
In the US, obligated federal government spending on AI increased from US$675 million to US$7.2 billion (£5.3bn) between 2024 and 2026 – an increase of almost 1,000%.
There has already been considerable debate – and some high-profile legal cases – regarding the ethics of AI companies training their models on the back catalogue of human creativity, only to rent the results back to us. Far less scrutinised is the question of AI companies developing technology using knowledge that only exists due to sustained public investment over many decades, via academics such as Nesterov.
The fact that big tech companies use complex international tax strategies to limit their tax liabilities adds to the sense that their aggressive defence of intellectual property rights is out of kilter with the publicly funded research that plays a key role in its development.
Technology built on public knowledgeIn most cases, academics work in publicly funded institutions on research grants that are largely funded by governments, whether through the Horizon Europe programme, the US National Science Foundation, or UK Research and Innovation. All of these bodies are ultimately funded by the taxpayer.
None of the rapid development in AI exists in a vacuum. It is built on decades of pioneering, blue-skies work on optimisation and neural networks, done by academics and largely funded by taxpayers at a time when the real-world application was still a distant dream.
Legal arguments around COVID vaccine patents are one example of how the private sector has tried to deny this public sector involvement – and a related share in any profits. So where is the public sector in this debate?
The EU is taking steps to secure control of its digital infrastructure, with a renewed focus on sovereignty in digital services. In the UK and elsewhere, a growing number of open-access mandates should mean that knowledge created by public funding stays public. While it can be used freely for commercial purposes, successful businesses would then theoretically pay back into the system via general taxation.
However, such knowledge flows beyond national borders. Efforts to capture value for reinvestment into the AI research landscape will be made harder by the fact that the tech companies' business models depend on lobbying governments hard to avoid regulation. Any efforts to make them pay more for upstream public research and development are likely to be strongly resisted.
In the case of Nesterov and his fast gradient methods, this foundational work has been done in European institutions – yet the AI companies dominating the market are overwhelmingly based in the US or China. It rankles when access to these models is then restricted by foreign companies and governments.

Legal Disclaimer:
MENAFN provides the
information “as is” without warranty of any kind. We do not accept any
responsibility or liability for the accuracy, content, images, videos,
licenses, completeness, legality, or reliability of the information
contained in this article. If you have any complaints or copyright issues
related to this article, kindly contact the provider above.
Comments
No comment